在 Amazon Bedrock 上用 Grok 4.7 构建长时程智能体
Build long-horizon agents with Grok 4.7 on Amazon Bedrock
AWS 发布教程,介绍如何在 Amazon Bedrock 上通过 us.xai.grok-4.7 或 global.xai.grok-4.7 推理配置文件调用 Grok 4.7,构建工具调用智能体。
原文用 72 次可复现的智能体运行,量化了 Grok 4.7 各推理档位在准确率与 token 成本之间的取舍。
SpaceXAI’s Grok 4.7 is now available on Amazon Bedrock, which offers a choice of foundation models (FMs) from multiple providers. According to SpaceXAI, Grok 4.7 is trained to work longer on more difficult tasks and knows when to check its own work. That matters most for agents, which carry a task through many steps and must verify what they find along the way.
An agent that works this way has to do more than look things up. It has to form a candidate answer, check it against what it has learned, and refine it until it fits. Grok 4.7 exposes a reasoning effort setting that controls how much deliberation happens before each response, and for agent workloads a practical question is which level to run.
In this post, we build a tool-calling agent on Grok 4.7 and evaluate it on three tasks that require search rather than lookup. The tasks are diagnosing a two-service outage from its alerts, scheduling maintenance under interacting constraints, and choosing an optimal set of migrations under a budget. Each task has exactly one correct answer, verified by brute force. We ran all three at every reasoning effort level, six times each, for 72 agent runs.
The agent answered 67 of the 72 runs correctly. At xhigh it answered all 18 correctly, and at low it answered 15 of 18 while using about an eighth of the output tokens. That gives a clear trade-off you can tune per request, and we show how to measure it on your own tasks and how to monitor it in production.
We report token counts rather than currency throughout. Token prices change, and the counts are what your own costs are derived from, so a measurement expressed in tokens stays valid.
What SpaceXAI reports about Grok 4.7
According to SpaceXAI, Grok 4.7 uses a larger base model than Grok 4.6 and was trained with a longer reinforcement learning run on a harder mix of tasks. This mix is weighted toward problems that take many hours to complete. SpaceXAI reports that the model is better at verifying its own work and at managing longer context.
SpaceXAI’s published benchmark results follow that emphasis. The largest reported gains over Grok 4.6 appear in the categories that measure sustained work rather than single-turn answers.
| Benchmark | Category | Grok 4.6 | Grok 4.7 |
| Terminal-Bench 4.0 | Multi-hour terminal work | 20.3% | 37.6% |
| EEBench | Electrical engineering | 53.0% | 64.0% |
| Harvey Legal Agent Benchmark | Legal work | 15.8% | 19.6% |
| CursorBench 4.0 | Longer-running coding | 40.4% | 46.3% |
| HealthBench Professional | Clinical reasoning | 48.5% | 56.7% |
| AA Briefcase v1.1 | Multi-hour office work | 1,546 | 1,657 |
Source: SpaceXAI, Introducing Grok 4.7 (https://x.ai/news/grok-4-7). Scores are as published by SpaceXAI at the time of the model launch.
Benchmarks show how a model performs across standard tasks. For your own workload, the useful next step is to measure on tasks shaped like yours, which is what the rest of this post walks through.
SpaceXAI lists a 500K token context window for Grok 4.7, with text and image input and text output. On Amazon Bedrock, the model supports configurable reasoning effort, tool calling, and structured output.
How you access Grok 4.7 on Amazon Bedrock
Grok 4.7 runs on the bedrock-runtime endpoint and is accessed through a cross-Region inference profile. Two profiles are available:
| Inference profile | Routing | Use when |
| us.xai.grok-4.7 | Within the US geography | You have US data residency requirements |
| global.xai.grok-4.7 | Commercial AWS Regions | You have no residency constraints and want the widest capacity |
Cross-Region inference routes requests across multiple AWS Regions, which gives you higher throughput without managing capacity Region by Region. Requests name one of the inference profiles rather than a bare model ID.
The model supports the OpenAI-compatible Chat Completions and Responses APIs, and the Amazon Bedrock Converse API. On Converse, reasoning is returned as a reasoningContent block alongside the text block. In inferenceConfig, set maxTokens only, and put model-specific parameters, such as reasoning effort, in additionalModelRequestFields.
For the current list of supported Regions, service tiers, and token prices, see the Grok 4.7 model card in the Amazon Bedrock User Guide and the Amazon Bedrock pricing page (https://aws.amazon.com/bedrock/pricing/).
Prerequisites
- An AWS account with access to Amazon Bedrock, and model access enabled for Grok 4.7.
- Python 3.9 or later, with
openai,boto3, andaws-bedrock-token-generatorinstalled. - AWS credentials configured in your environment.
Your AWS Identity and Access Management (IAM) identity needs bedrock:InvokeModel on both the inference profile and your account’s default project:
arn:aws:bedrock:{region}::inference-profile/us.xai.grok-4.7or theglobal.equivalent.arn:aws:bedrock:{region}:{account-id}:project/default.
Include both resources in the policy statement. The default project permission is required in addition to the inference profile.
Connect to the model
For production use, we recommend generating a short-term bearer token from your existing AWS credentials, so authentication stays tied to your IAM identity and no long-lived secret is stored:
from aws_bedrock_token_generator import provide_token
from openai import OpenAI

REGION = "us-west-2"
MODEL_ID = "us.xai.grok-4.7"

client = OpenAI(
    api_key=provide_token(region=REGION),
    base_url=f"https://bedrock-runtime.{REGION}.amazonaws.com/openai/v1",
    timeout=360,
    max_retries=0,  # retries are handled explicitly, see "Build in retries" below
)
Reasoning tokens count as output tokens and draw down max_completion_tokens before the answer text is produced, so size the limit to leave room for both. If the limit is reached during reasoning, the response returns without answer text, so check for empty content in agent code and raise the limit if you see it. Our runs used a limit of 32,768 tokens, which left headroom at every effort level.
Grok 4.7 supports four effort levels: low, medium, high, and xhigh. Effort levels can change between model versions, so it is worth confirming them against the service rather than hardcoding a list:
def supported_effort_levels(candidates=("none", "low", "medium", "high", "xhigh", "max")):
    supported = []
    for level in candidates:
        try:
            client.responses.create(model=MODEL_ID, input="Say OK.",
                reasoning={"effort": level}, max_output_tokens=2048)
            supported.append(level)
        except Exception as exc:
            if "unsupported_value" not in str(exc) and "invalid_value" not in str(exc):
                raise
    return supported


print(supported_effort_levels())  # ['low', 'medium', 'high', 'xhigh']
Design tasks that need reasoning
Many agent evaluations test diligence: read a record, filter it, add it up. Those tasks are worth having, but to see what reasoning effort contributes, a task has to require search: the answer can’t be read off the data, it has to be proposed and then checked.
We built a synthetic environment of 20 services, exposed through seven tools, and three tasks on top of it. Every task has exactly one correct answer, and each is built so that a quick heuristic is not enough to find it.
| Task | What the agent has to do | What makes it a reasoning task |
| two_fault_diagnosis | Two services failed silently at 03:00 and 12 others raised alerts. Identify the two that failed | Failed services raise no alerts, so the answer is not among the alerting services. 190 possible pairs, and only one explains exactly the alerts observed |
| maintenance_schedule | Patch eight services over four nights, two per night, under ten constraints and a rule that two services from the same team never share a night | 2,520 possible schedules, one valid. The team rule depends on data the agent has to look up |
| migration_budget | Choose candidates to migrate that maximize risk reduction within a budget, including transitive prerequisites | 53 feasible sets, one optimal. Picking the best ratio first gives a set nine points short of the optimum |
Four practices keep a measurement like this trustworthy, and they apply to most agent evaluations.
State every rule the grader relies on. If the prompt leaves an edge case open, a reasonable answer can be scored as wrong, and the evaluation ends up measuring the specification rather than the model. The diagnosis prompt, for example, says explicitly that a failed service raises no alert of its own.
Prove each task has one answer. Each environment is small enough to enumerate, so we checked every candidate answer before running anything. For the schedule, that is a few lines:
import itertools

ALL_SLOTS = sorted(set(itertools.permutations([1, 1, 2, 2, 3, 3, 4, 4])))

def valid_schedules(services, constraints):
    return [s for slots in ALL_SLOTS
        if satisfies(s := dict(zip(services, slots)), constraints)]

assert len(valid_schedules(SERVICES, CONSTRAINTS)) == 1  # exactly one answer
assert len(valid_schedules(SERVICES, CONSTRAINTS_WITHOUT_TEAM_RULE)) > 1  # the rule matters
Grade a required final line, not the whole response. Each prompt asks the agent to end with a line such as FINAL: auth, checkout. The grader reads only that line, so a response that discusses other candidates while explaining its reasoning is graded on its conclusion:
def final_line(answer):
    lines = [l for l in (answer or "").splitlines() if "FINAL" in l.upper()]
    return lines[-1] if lines else None
Track format separately from correctness. A missing final line is a different signal from an incorrect one. In our runs, all 72 responses included a gradeable final line.
Constrain tool parameters with an enum where the valid values are known, so every tool call targets a real resource:
TOOLS = [
    {"type": "function", "function": {
        "name": "get_dependencies",
        "description": "Services that one service directly depends on.",
        "parameters": {
            "type": "object",
            "properties": {"service": {"type": "string", "enum": SERVICE_NAMES}},
            "required": ["service"],
        }}},
    # The remaining six tools follow the same shape.
]
The system prompt is deliberately short, and asks the agent to check its answer before giving it:
AGENT_SYSTEM = (
    "You are an infrastructure analyst agent. Use the tools to gather facts and never guess "
    "a value you can look up. Before answering, check your answer against every rule in the "
    "task. End with the FINAL line exactly as the task specifies."
)
The agent loop is a standard tool-calling loop: call the model with reasoning_effort set, execute each returned tool call, append the result keyed by tool_call_id, and repeat until the model stops requesting tools. Tracking prompt_tokens and completion_tokens across the loop gives the token counts reported in the following section.
Results
Six runs of each task at each effort level, 72 runs in total. The agent answered 67 correctly.
| Task | low | medium | high | xhigh |
| two_fault_diagnosis | 5 of 6 | 6 of 6 | 6 of 6 | 6 of 6 |
| maintenance_schedule | 5 of 6 | 5 of 6 | 5 of 6 | 6 of 6 |
| migration_budget | 5 of 6 | 6 of 6 | 6 of 6 | 6 of 6 |
| All three tasks | 15 of 18 | 17 of 18 | 17 of 18 | 18 of 18 |
| Per run | low | medium | high | xhigh |
| Mean output tokens | 1,184 | 6,430 | 6,778 | 9,147 |
| Output tokens relative to low | 1.0x | 5.4x | 5.7x | 7.7x |
| Mean tool calls | 17.2 | 18.7 | 17.8 | 18.1 |
| Median elapsed time | 18s | 98s | 89s | 106s |
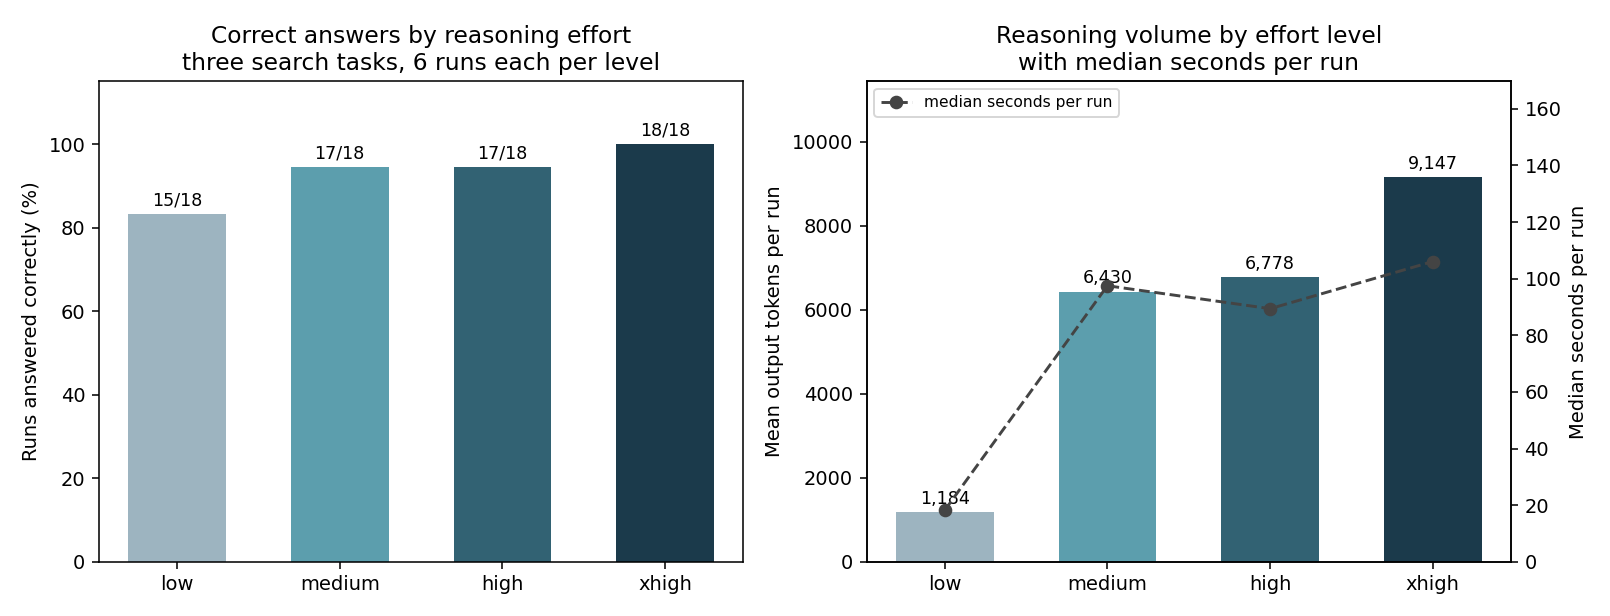
Figure 1: Share of runs answered correctly at each reasoning effort level (left), and mean output tokens per run with median seconds per run overlaid (right)
Three observations.
xhigh answered every run correctly. All 18 runs across the three tasks were correct at xhigh, and medium and high answered 17 of 18 each. With six runs per task and level, the differences between levels are indicative rather than statistically conclusive, and the direction was consistent across all three tasks.
Effort changes how much the agent reasons, not how much it explores. Tool calls were essentially flat, between 17.2 and 18.7 per run at every level. The agent gathered the same facts regardless of effort, and what changed was how much reasoning it applied to them, with output tokens rising from 1,184 at low to 9,147 at xhigh.
low offers a strong cost-to-quality ratio. At low, the agent answered 15 of 18 runs correctly using about an eighth of the output tokens of xhigh, with a median run of 18 seconds. Where a slightly lower completion rate is acceptable, or where answers are reviewed downstream, low is an efficient choice. Where every answer needs to be right first time, higher levels are the safer default.
How effort level shapes the answer
The tasks were designed around a specific kind of difficulty, and looking at how each effort level handled them clarifies when the extra reasoning is worth it.
Optimization. The migration task rewards considering combinations rather than ranking options one at a time. Selecting the candidates with the best individual ratios produces a reasonable answer that is nine points short of the optimum. At medium and above, the agent found the optimal set in all 18 runs.
Hypothesis testing. The diagnosis task requires checking a candidate pair in both directions: every alert has to be explained, and every service that stayed silent has to be consistent with the answer. At medium and above, the agent identified the correct pair in all 18 runs.
Constraint satisfaction. The scheduling task combines ten listed constraints with a team rule that depends on looked-up ownership data. xhigh produced the valid schedule in every run, and this was the task where the highest level made the clearest difference.
The pattern across the three is that additional reasoning effort is most valuable where the agent has to weigh several candidate answers against each other, rather than follow a single path to the result.
Monitoring reasoning in production
In production you don’t have a known answer to grade against, but you do know how many output tokens and tool calls each run used. Those give you a useful operational signal.
Correct runs at each level stay above a clear floor of reasoning volume. Every correct run at medium and above used at least 1,739 output tokens, and the typical run used several thousand. A run that makes no tool calls, or that produces far less output than is normal for its level, is worth flagging for review:
def flag_for_review(run, baseline):
    """baseline: output tokens of graded, correct runs at the same effort level."""
    reasons = []
    if run["tool_calls"] == 0:
        reasons.append("made no tool calls")
    if run["output_tokens"] < 0.2 * min(baseline):
        reasons.append(f"used {run['output_tokens']} output tokens, "
            f"under a fifth of the lowest correct run ({min(baseline)})")
    return reasons
Calibrate the baseline from runs you have graded, per task and per effort level, then apply it to runs you have not. Treat a flag as a prompt to inspect or re-run. At low, where every run is brief, output volume is a weaker signal, so pair it with spot checks.
Asking the agent to verify its answer in the system prompt is worth keeping, because it makes the agent’s reasoning straightforward to follow when you review a run. Pair it with automated grading wherever a known answer exists, so that quality is measured independently of the transcript.
Choosing a reasoning effort
These results suggest a few practical rules.
Match effort to the kind of task. Tasks that involve search, optimization, or testing a hypothesis benefit most from medium or higher. Tasks that follow a single path, or whose answers are reviewed downstream, can run efficiently at low.
Set effort per request, not per agent. Effort is a request parameter, so an agent can run its planning and verification steps at a higher level and its mechanical steps, such as formatting a tool result, at low. That combines much of the reliability of a higher level with a lower token cost.
Measure on your own tasks, with repeats. A single run per configuration gives a single observation. Repeating each configuration several times shows how consistent it is.
Monitor reasoning volume. Output tokens and tool calls per run, tracked by effort level, give you an early signal to review a run before its result is used.
Limitations of this measurement
Six runs per task and effort level. Enough to show a consistent direction across three tasks, not enough for a confidence interval. Treat the differences between levels as indicative.
A synthetic environment. The tools read from data generated in code, which is what makes it possible to prove each task has exactly one answer and to grade automatically. Real tools add latency, partial results and errors, none of which are tested here.
Minutes, not hours. Median run time ranged from 18 seconds at low to 106 seconds at xhigh. This is a scaled-down proxy for long-horizon work. The method transfers. The absolute figures do not.
One model version, one Region, one prompt per task. Different phrasings of the same task may change the results, which is part of why stating every rule explicitly matters.
Token counts, not costs. To convert to currency, apply the current rates for your inference profile and service tier from the Amazon Bedrock pricing page. The Global and US Geo profiles are priced differently, and the Flex and Priority service tiers apply multipliers.
Operational controls for agent workloads
Build in retries. Agents that issue a high volume of calls should treat retries as part of the design. Set a request timeout, retry only errors that are retryable, back off exponentially with jitter, and honor a Retry-After header when one is returned:
import random, time

RETRYABLE = {408, 429, 500, 502, 503, 504}

def call_with_backoff(fn, attempts=7, base=4.0, cap=180.0):
    for attempt in range(1, attempts + 1):
        try:
            return fn()
        except Exception as exc:
            status = getattr(exc, "status_code", None)
            retryable = status in RETRYABLE or "timed out" in str(exc).lower()
            if not retryable or attempt == attempts:
                raise
            time.sleep(random.uniform(base, min(cap, base * 2 ** attempt)))
On-demand throughput scales up over time, so ramp a new high-volume workload gradually rather than starting at full rate.
Auditing a run. Model invocation logging writes request and response data to Amazon Simple Storage Service (Amazon S3) or Amazon CloudWatch Logs. This gives you the full transcript of runs you want to review after the fact.
Monitoring reasoning volume at scale. Amazon CloudWatch metrics give you the aggregate view of token usage, which is where the per-level baselines described earlier become something you can alarm on.
Attributing spend across agents. Cost itemization in AWS Cost Explorer and the AWS Cost and Usage Report breaks usage out per model, which combined with per-task token counts gives you both unit economics and the aggregate bill.
Matching cost to urgency. Service tiers are set per request, so one deployment can send an overnight analysis through the Flex tier and an interactive request through Priority. For a workload that runs at a higher effort level, tier selection is a further lever on cost.
Choosing a routing profile. Cross-Region inference widens the capacity pool a long run draws from. The Global profile serves from your choice of commercial AWS Region and is typically priced lower per token than geographic routing. The US profile keeps processing within the United States. Choose based on your data residency requirements as well as cost.
Clean up
The examples in this post do not create billable AWS resources beyond per-request token usage. If you generated a long-term Amazon Bedrock API key, delete it in the Amazon Bedrock console when you are finished, because it remains valid until revoked. Short-term tokens generated from IAM credentials expire on their own.
If you enabled model invocation logging to Amazon S3 while testing, review the bucket and remove objects you no longer need.
Conclusion
SpaceXAI trained Grok 4.7 to work longer on more difficult tasks and to know when to check its own work. On three tasks that required search rather than lookup, the agent answered 67 of 72 runs correctly, and every run at xhigh. Because reasoning effort is set per request, you can choose where each step of an agent sits on the trade-off between thoroughness and token cost.
Three things are worth carrying into your own evaluation. Design tasks with one provable answer and state every rule the grader depends on. Repeat runs, so you see how consistent each configuration is. And monitor output tokens and tool calls by effort level, so you have an operational signal alongside your quality measurements.
Further reading
- Introducing Grok on Amazon Bedrock
- Grok 4.7 is now available on Amazon Bedrock
- Route model inference requests across AWS Regions with cross-Region inference
- Getting started with Amazon Bedrock
- Chat Completions API
- Amazon Bedrock pricing
- Introducing Grok 4.7 (SpaceXAI)
About the authors

Suheel Farooq
Suheel is a Principal Solutions Architect at AWS, specializing in artificial intelligence, machine learning, and generative AI. He helps Foundation Model Provider customers design, build, modernize, and scale their AI/ML and generative AI workloads on AWS — from bringing foundation models to Amazon Bedrock to optimizing training and inference and building Agentic AI solutions. His experience spans the AWS AI/ML and generative AI portfolio, particularly Amazon Bedrock, Amazon Bedrock AgentCore, and Amazon SageMaker AI. In his free time, Suheel enjoys working out and hiking.

Anirban Gupta
Anirban is a Principal Engineer at AWS based in Seattle, USA, where he focuses on the design of secure, high-scale model-serving infrastructure for Amazon Bedrock. He has driven the technical work behind several foundation-model launches on the platform. Prior to joining Amazon Bedrock, he was a Principal Engineer on AWS Outposts, building hybrid on-premises cloud infrastructure.

James Wang
James is Senior Product Growth Manager at SpaceXAI. Previously, he was Director of Product Marketing at Cerebras, where he launched Cerebras Inference and the CS-3 AI accelerator. Before that James was lead AI analyst at ARK Invest. He started his career at NVIDIA, launching the first CUDA-capable GPUs in the early days of deep learning.

Ikenna Izugbokwe
Ikenna is a Principal Solutions Architect at AWS specializing in networking, containers, and AI infrastructure. He guides model providers through scaling their training and inference systems while enabling rapid deployment of evolving frontier models on AWS. His work increasingly spans agentic AI – building reliable, cost-efficient multi-agent systems and the inference infrastructure behind them in production.
来源:AWS Machine Learning Blog · aws.amazon.com